As I type this, my main is Claude Code and my secondary is omp. Both of these seem to do a pretty good job of choosing an appropriate model for subagent tasks, especially if I ask and/or save it as a guideline in project memory.
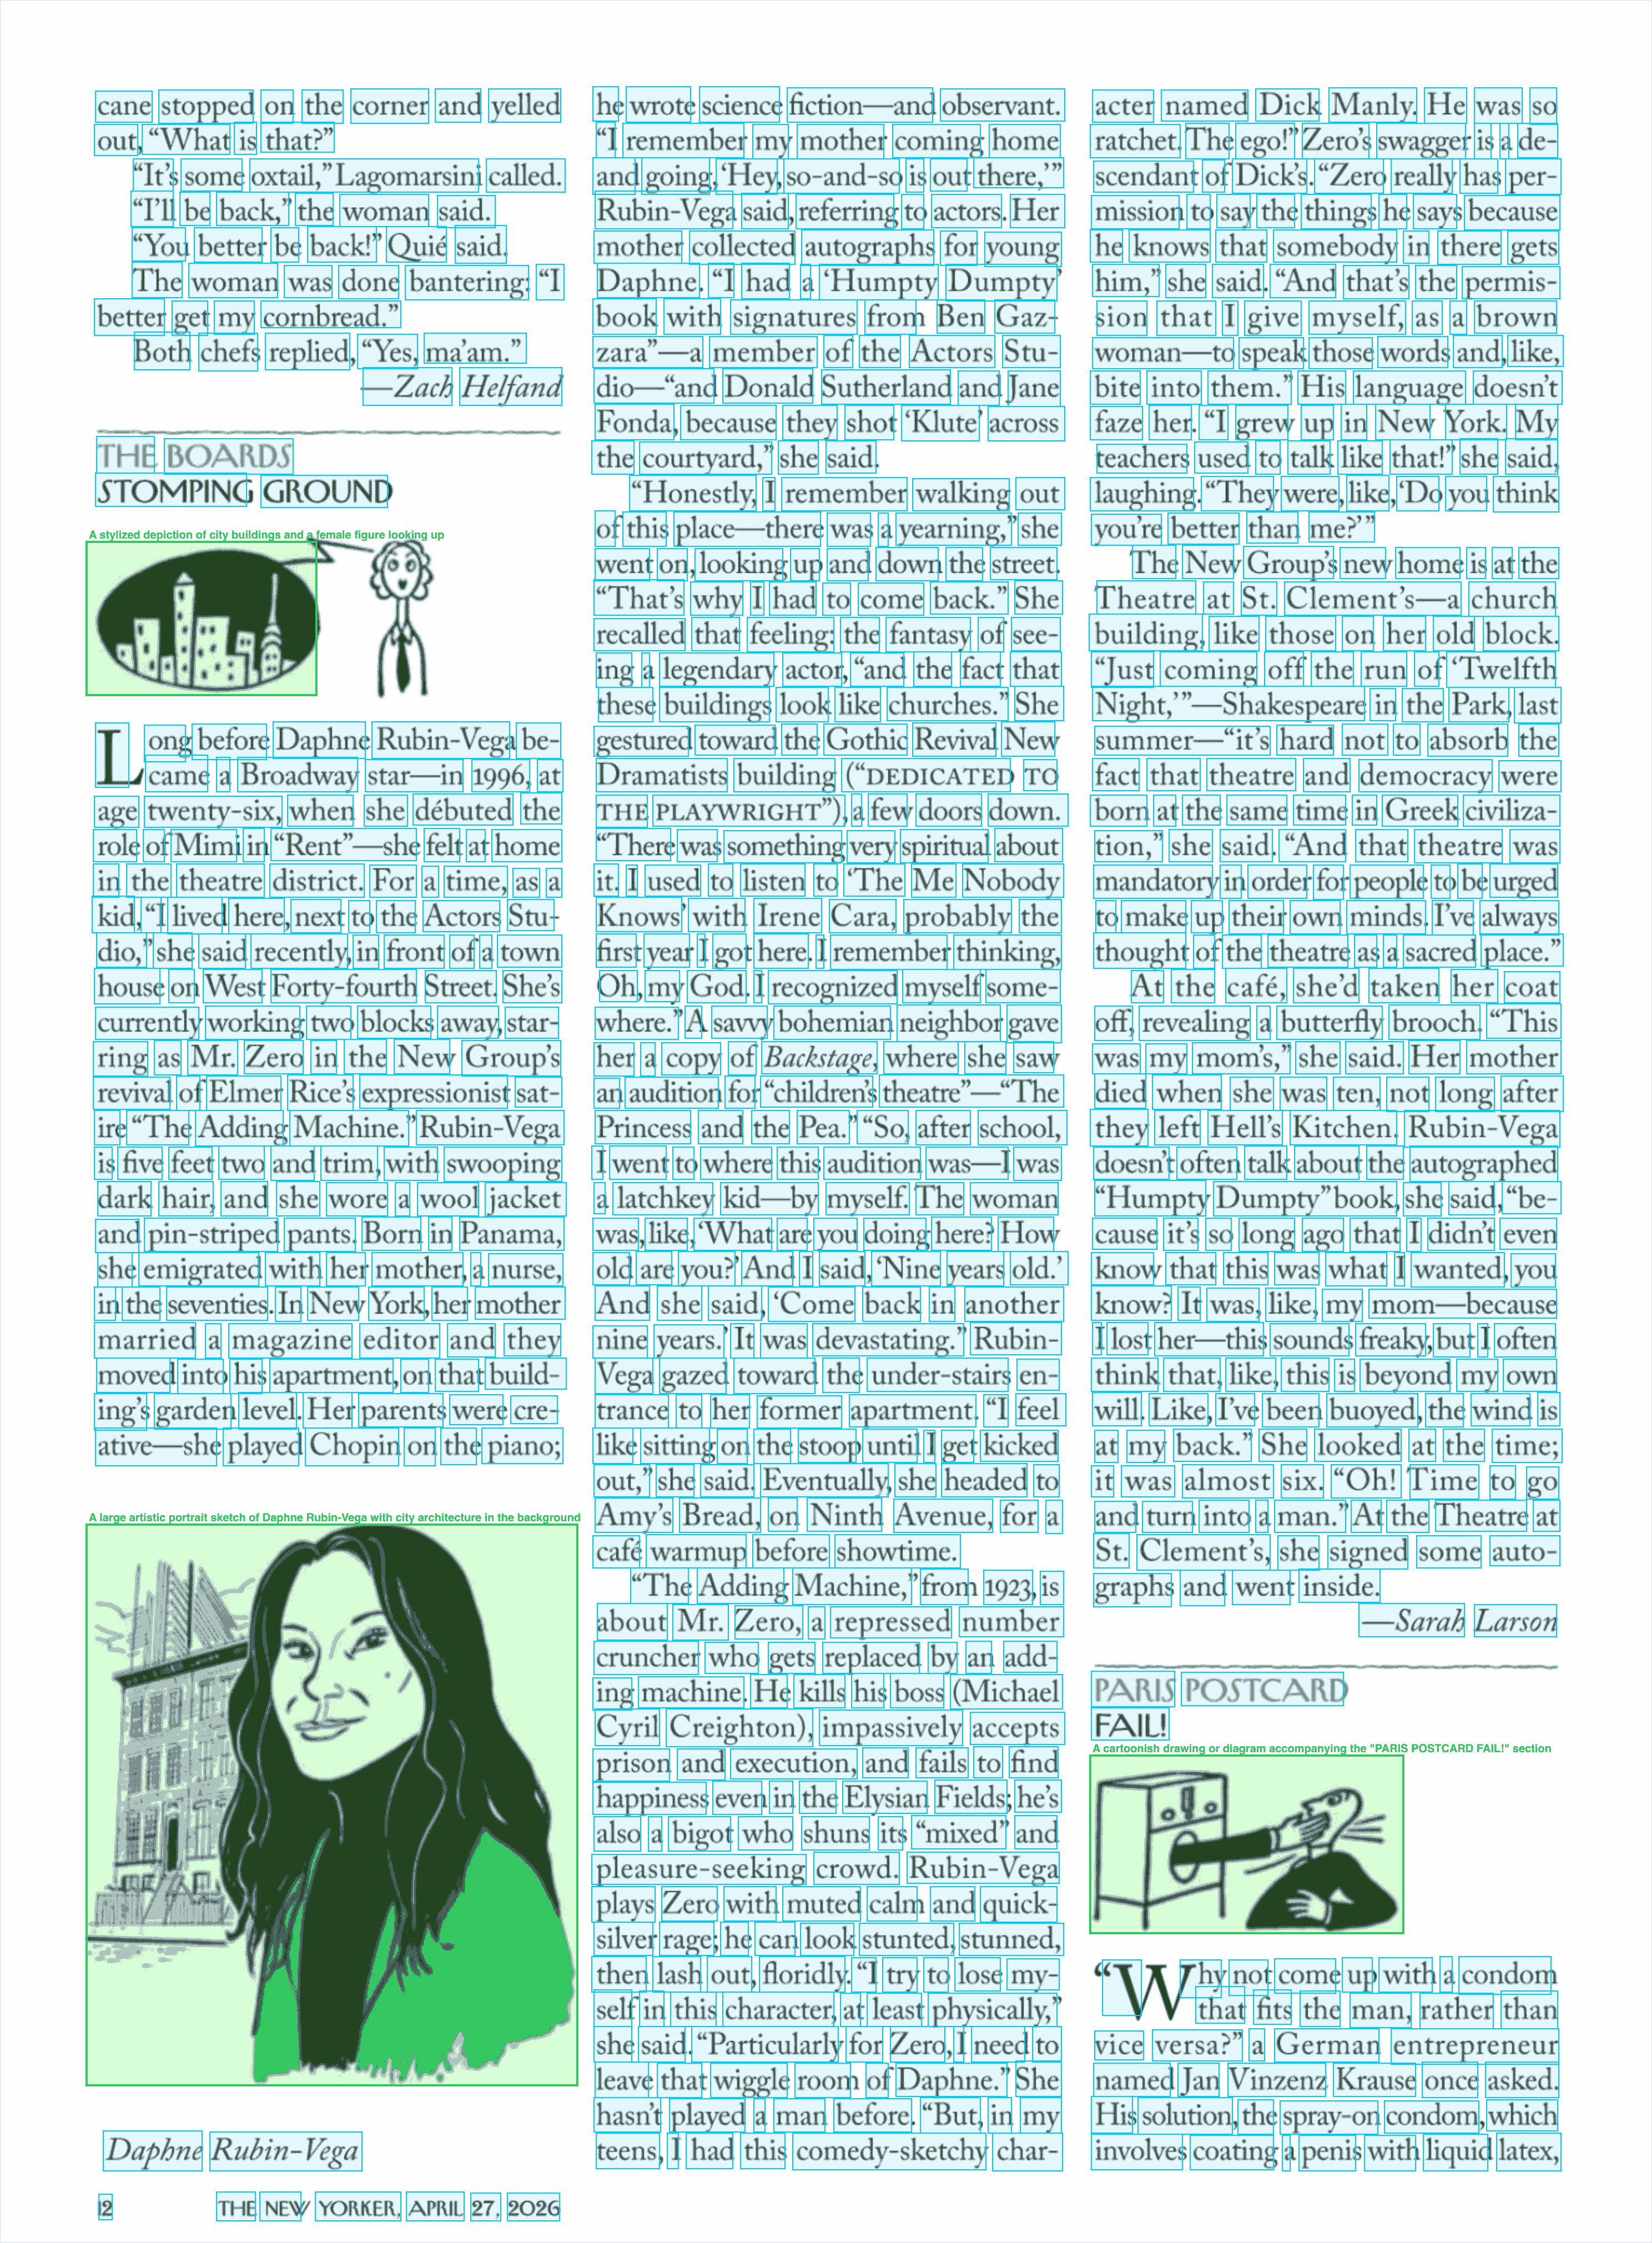
The PP-DocLayoutV3 [1] bounding boxes are pretty good in my experience, if you want boxes around individual document headings or paragraphs. If you want boxes around individual words, similar to what's shown in the Interfaze screen shot [2], Apple has a LiveText "token" model that's proprietary but free/bundled with macOS and iOS. There are easy to use Python bindings here: https://github.com/straussmaximilian/ocrmac
I presume that some otherwise-great OCR models (like Chandra) have terrible bounding boxes because generating good bounding boxes just wasn't a training priority. A lot of people are using OCR models to bulk-process documents without a lot of care for how the layout is preserved. It matters a lot if (e.g.) you want to be able to update and re-print old documents, but it doesn't matter if you are just transcribing whole documents for indexing/chunking/translation.
For sure there a tons of OCR bounding models and tons of other models like SAM 3 for segmentation.
Interfaze is a more powerful version of them combined into a single model, you can run multi turn tasks like extract all the text and object from this document then translate or generate a report.
It's like getting the best of both worlds from pure DNN/CNN models like Paddle and the flexibility and nuace of an LLM while outperforming both in accuracy.
Curious about background removal with BiRefNet. Would you consider it the best model currently available? What other options exist that are popular but not as good?
I'm far from an expert in this area. I've also tried Bria RMBG 1.4, Bria RMBG 2.0, older BiRefNet versions, and I think another I forgot the name of. The fact I'm removing backgrounds that are predominantly white (a sheet of paper) in first place probably changes things significantly. So it's hard to extrapolate my results to general background removal.
BiRefNet 2 seems to do a much better job of correctly removing backgrounds in between the contents outline. So like hands on hips, that region that's fully enclosed but you want removed. It's not just that though, some other models will remove this, but they'll be overly aggressive and remove white areas where kids haven't coloured in perfectly — or like the intentionally left blank whites of eyes for example.
I'm putting these images in a game world once they're cut out, so if things are too transparent, they look very odd.